Reverse-engineer any database into a clean data model
Connect Postgres, MySQL, Snowflake, BigQuery, Redshift or Databricks. offdataai reads the catalog, finds the relationships nobody declared, classifies every table, and builds a project you can modernize.
- From $1/month
- 8 SQL targets
- 174 templates
Suggested relationships
See it in action
A narrated walkthrough, recorded in the real app.
Three steps, minutes not months
Describe or import
Answer a short interview, open a template, draw on the canvas or connect a live database.
Review a validated model
Keys, grain, history and PII are checked before any code is written. Refine it in plain English.
Ship and keep it current
Native DDL, dbt, seeds, docs and an ontology. Push to Git, diff versions, generate migrations.
Why teams choose offdataai
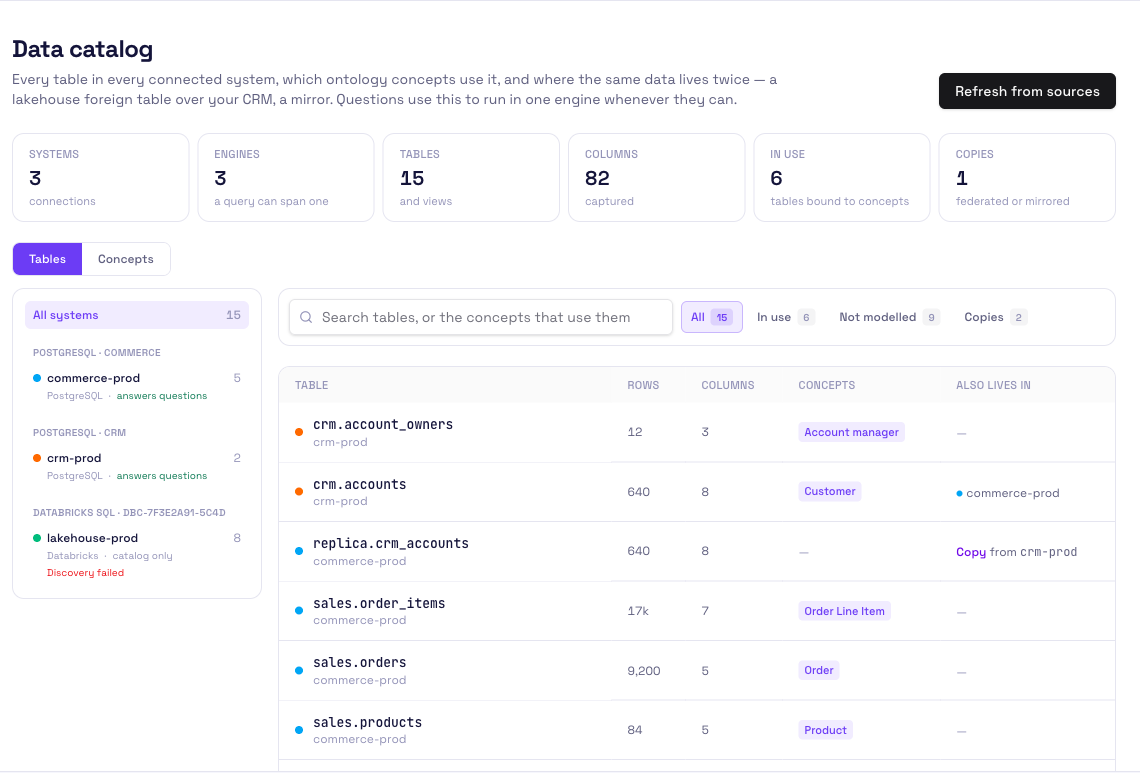
A live database read into the catalog, tables classified and keys suggested
- 01
Most real databases were never designed on a whiteboard.
- 02
Foreign keys are missing, staging tables sit next to facts, and the only documentation is in someone's head.
- 03
Rebuilding a model from that by hand takes weeks.
- 04
The Database Modeler does the archaeology for you.
- 05
It reads only the catalog, never your rows, then infers undeclared relationships with a confidence score and the evidence behind each one.
- 06
Every table is classified as a fact, dimension, bridge, lookup, staging table and more, with grain, PII and history detected.
- 07
Review the result, then build a project: mirror the schema 1:1, or let AI remodel it as a star schema or Data Vault for the warehouse you are moving to.
The code it writes, not a sketch
This is the shape of what offdataai generates here, straight from the validated model. Copy it, download it, or push it to Git.
- Catalog-only introspection
- Relationship inference you can review
- Automatic classification
1source snowflake · ANALYTICS.PUBLIC2tables 142 read (catalog only, no rows)34inferred relationships5 orders.cust_id → customers.id 0.94 ✓6 order_items.order_id → orders.id 0.97 ✓7 payments.ord_ref → orders.id 0.71 review89classification10 orders fact grain: one row per order11 customers dimension SCD 2 · PII: email, phone12 order_items fact grain: one row per line13 stg_orders_raw staging excluded1415build remodel → Kimball · target: snowflake
What the Database Modeler does
Catalog-only introspection
Tables, views, columns, keys, indexes, constraints and comments, read from the catalog. No rows are selected, and credentials are encrypted at rest.
Relationship inference you can review
Undeclared foreign keys are suggested with a confidence score and evidence. Accept, reject or bulk-accept; only accepted ones are used.
Automatic classification
Facts, dimensions, bridges, lookups, staging and audit tables, plus column roles, PII, SCD type, grain and subject area.
Mirror or remodel
Keep the schema 1:1 for documentation, or remodel it as a Kimball star schema or Data Vault 2.0 for a new platform.
Schema drift
Re-analyze a source and compare snapshots to see exactly what changed before you rebuild.
Write back to Unity Catalog
On Databricks, learn joins from query history, apply the keys, descriptions and PII tags you approved, and publish a metric view so Genie stops double-counting.
From database to ontology
Use an imported schema as an ontology source and merge it with your warehouse model into one business vocabulary.
0
Validated templates
0
SQL targets
0
Modeling paradigms
0+
Industries covered
Generates native SQL and dbt for 8 platforms · connects live to Snowflake, Databricks, BigQuery, Redshift and Postgres
 RedshiftPostgreSQL
 Synapse
 FabricDuckDB
 dbtSnowflakeBigQueryDatabricksRedshiftPostgreSQLSynapseFabricDuckDBdbt
Frequently asked questions
Which databases can the Database Modeler read?
Does offdataai read my data?
What if my database has no foreign keys declared?
How are tables classified?
What can I build from an imported schema?
Can it detect schema changes?
What does it add for Databricks?
Which plan includes the Database Modeler?
Explore offdataai
- AI Data ArchitectHire Atlas by the hour: voice or text, 43 languages, read-only.
- Semantic layerGoverned metrics, compiled to SQL for people and AI agents.
- Context layer for AI agentsConcepts, metrics, join paths and docs for agents over MCP.
- Data catalogEvery table and column, which concepts use it, where it's copied.
- Data modeling tools comparedDesktop, diagram, code-first and AI-native tools side by side.
- Ontology builderTurn a data model into a published business ontology.
Part of the offdataai platform
The business context behind accurate AI answers, built from the data model up.
- 01DesignLogical, physical and dimensional models.
- 02GenerateSQL, dbt, documentation and migrations.
- 03DefineBusiness metrics, semantic models and ontology.
- 04ConnectReal warehouse schemas and metadata.
- 05GovernDrift, impact analysis, tests and approvals.
- 06ActivateMake trusted context available to AI agents.
This page covers Design and Connect. Every stage works on the same model, so what you design here carries through to the rest.
Give your AI agents context they can trust.
Design the model, define what your metrics mean, and serve that context to every agent and BI tool, on the warehouse you already run.